Keeping today's records for tomorrow's tools.
Some of the tools that will read your records have yet to be written, and the systems you use today each keep what suits them, for as long as it suits them: build logs expire, the ticket goes with the tracker, the branch is squashed. Ranke keeps the material itself — every record as it arrived, with who filed it, when, and what it was built from. It stays structured and navigable in the meantime, so an agent can walk the archive, and a scoped export hands what a question needs to the analysis system of your choice.
What an archive keeps
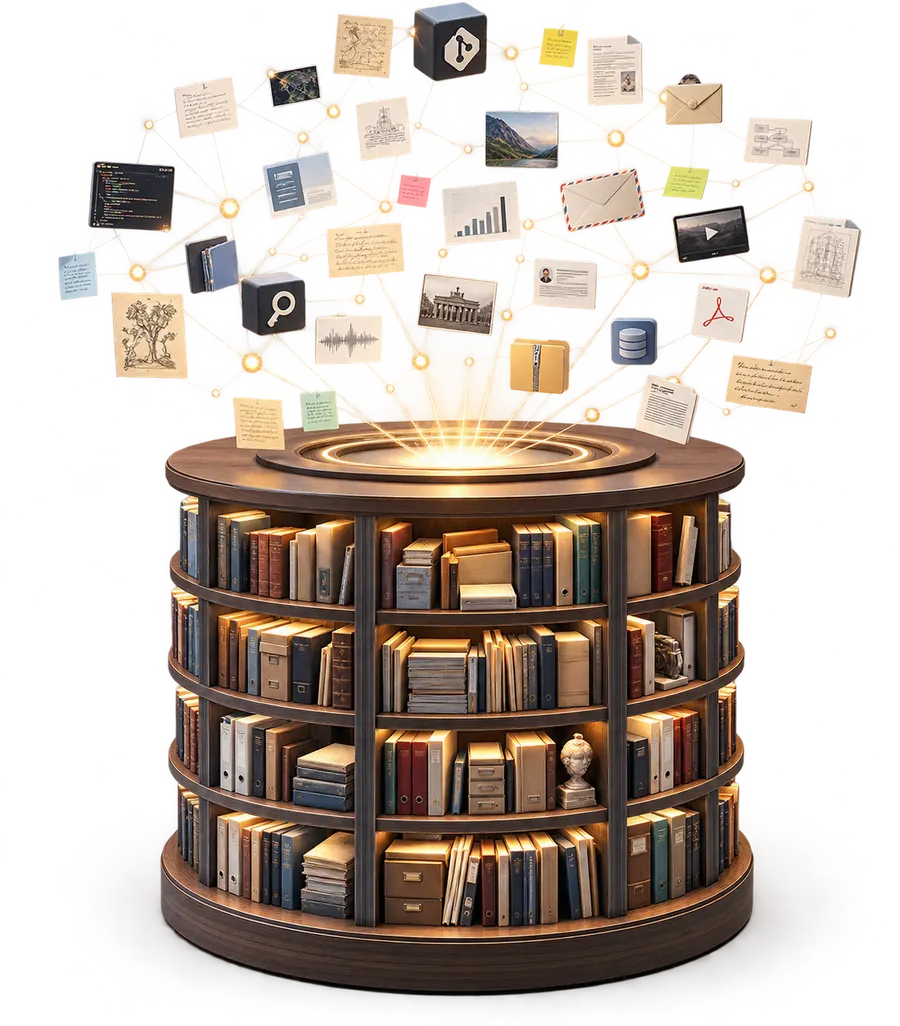
An archive is a collection of records: letters, photographs, minutes, recordings.
Each one was taken in, and the taking-in was itself recorded.
So every record carries two dates: when it entered the archive and its presumed date of origin.
It carries who put it there. It carries what it is. None of this describes the world the record speaks about; it describes the record, and that is what makes the record usable as evidence rather than as information.
Nothing changes after entering the archive. A document that turns out
to be wrong keeps its place; a later record says so, and both stay
readable. Contradiction is part of what the archive holds, because
which account is right is often decided long after both were filed.
Every record belongs to a body of material. Cataloguing, summaries and analyses
are filed too, each saying what it drew on.
A century of that work leaves a structure, and the structure is what makes anything findable.
Archives have done this since the nineteenth century.
Digital systems keep history: git every version of a file, an issue tracker every comment,
a build system its logs. Each keeps its own, under its own policy: one squashes, one prunes
after 90 days, one is append-only, and several cannot be exported at all. The history is
scattered, and no system holds what runs across them.
What Ranke does with it
Ranke-Graph takes the archival form literally. Everything enters as a claim: a file, a commit,
a scan result, a message. A claim holds the bytes as they were, the time it entered, who put it
there, and edges to the claims it was built from. Nothing is overwritten or removed, and no
claim can be written without saying what it rests on.
That constraint is where the order comes from. The structure is the citations themselves, so there
is no catalogue to maintain, and following them always ends at something that entered from
outside. Whatever an agent or a colleague answers from the archive, the path back to the
original record is part of the answer.
Ranke-Graph is a format. The graph is the content, and any store that holds
bytes under a key can hold it: a filesystem, S3, Postgres, Neo4j, or more than one at once. RankeDB
serves it and decides who may read and write. Without RankeDB the archive is still a set of
self-describing files.
Answering is a tool's job, and the archive gives it two ways in. A client traverses the
graph in place: a prompted agent, a worker built on the SDKs, anything that can follow an
edge to what a claim cites. Or an export hands a scoped cut to a system built for the
question — this year's mail for one, a release's evidence for another. The archive stays
behind both, so a system adopted next year, or one still to be written, starts from the
whole record.
Choosing what goes into a cut is archive work in itself, and the graph carries enough
structure to do it here. Every claim states what it rests on, so the archive can be
searched and walked without a knowledge system on top: an agent gathers the records a
question needs and says what it drew on. That selection can be filed as a claim of its
own, and a later reading can then see how the cut was made.
Available now
Snapshot a git repository
Import a repository, the full history or a single commit. Each file becomes a claim of its own, linked to the commit, and the commit to the repository. The snapshot restores byte-identical to the original.
Ask when a vulnerable dependency first entered, and the answer names the commit, the author and the moment, with the bytes to check it against.
ranke-git
Next
More adapters, and a generic export
Email and chat threads, issue trackers, CI build logs, and security scan reports each need an adapter: a small program that reads a source and turns it into claims. The export runs the other way — a filtered cut of the archive, serialised into formats other systems already read.
An agent can extend the graph as readily as read it. Its analysis runs on a branch of its own: it adds claims, cites the records it read, and leaves the sources untouched. Whoever reviews it later can see every record the analysis drew on.
Similar technologies
Twenty systems keep history in ways that overlap with this one, and several of them are
further along at the job described above. The
neighbours page takes each in turn: what it is for, where it
goes further than Ranke, where Ranke goes further, how the two would compose, and the terms
it comes on.
What it aligns with
W3C PROV-DM
The standard vocabulary for provenance: entities, activities, agents. A
Ranke-Graph maps onto it, and holds the provenance in the same graph as the content.
CASE and UCO
How a cyber investigation is described: chain of custody, meaning who
handled the data, when and where, and chain of evidence, meaning which tools treated it. The
same discipline, written for investigators.
EDTF
The Library of Congress's format for a date known only approximately,
which is what the presumed date of origin needs.